
About Me
I am a postdoctoral research fellow at Fudan University, working with Yixin Cao. I received my Ph.D. from Singapore Management University, supervised by Yixin Cao and Qianru Sun. My research focuses on developing generalizable, reliable, and effective methods for the evaluation and self-improvement of Large Language Model (LLM) systems.
Research Interests
LLMs Evaluation
- Automated evaluation data generation
- Reliable evaluator development
LLMs Improvement
- Adaptive learning strategies
News
- Oct 2026New preprint “Belief-Trajectory Energy: Measuring the Path to a Prediction”, with an interactive project page.
- Aug 2026Two papers were accepted to EMNLP 2026.
- May 2026New preprint “OpenSkillEval: Automatically Auditing the Open Skill Ecosystem for LLM Agents” is out.
- Feb 2026Two papers were accepted to ICLR 2026; “FRABench and UFEval” is selected for an oral presentation.
- May 2025Two papers were accepted to ACL 2025 Main Conference.
- Apr 2025Our paper “Revisiting LLM Evaluation through Mechanism Interpretability” is published.
- Jan 2025One paper was accepted to NAACL Findings.
- Oct 2024One paper was accepted to NeurIPS 2024 Datasets & Benchmarks Track.
- Oct 2024Two papers were accepted to EMNLP 2024 Findings.
- Jun 2024Two papers were accepted to ACL 2024 (one Main Conference, one Findings).
- Oct 2023One paper was accepted to NeurIPS 2023 Datasets & Benchmarks Track.
Publications
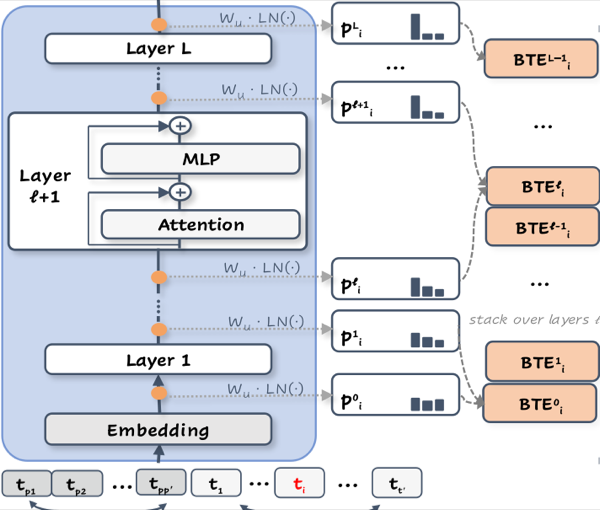
A belief climbs the layers; how much it is revised on the way up is the measurement.

An auditor sweeps the open-skill shelf — most pass, one gets flagged.

Text, images, or both interleaved — one judge grades them all, aspect by aspect.

Great score — but peek inside, and only a few neurons are doing the work.

One question, untangled into two axes — language and culture — then graded cell by cell.

Benchmarks go stale; this one refreshes itself to v2, automatically.

Mistakes loop back as lessons — until the ✗ turns into a ✓.

Trust its own memory, or follow the prompt? A tug-of-war in slow motion.

A generator writes, a reader reads — together they climb above the solo baseline.

A language model sets the exam, grades the answer, and stamps the score.
Services
Conference Reviewer
- Association for Computational Linguistics (ACL) 2023, 2024, 2025
- Empirical Methods in Natural Language Processing (EMNLP) 2023, 2024
- International Conference on Learning Representations (ICLR) 2024, 2025
- Conference on Language Modeling (COLM) 2024